Qwen3.8 Max for Marketing: Tested on a Real Ad Brief
We gave Qwen3.8 Max and six other models one TikTok ad brief. See its hooks, 15-second script and compliance notes, plus speed and credits per run.
Qwen3.8 Max is the most thorough model we tested for ad copy: on the same TikTok brief, it was the only one to add a ready-to-post caption, a plan for shooting hook variants, a "results vary" disclosure and an #ad reminder for creators. It was also the second-slowest of the seven (only Gemini 4 Argon took longer): about 90 seconds before any text appeared and about 135 seconds in total, so it suits a finished creative brief more than quick back-and-forth ideation.
Qwen3.8 Max is one of the chat models you can pick in BuzzVideo AI's Marketing Agent, alongside Gemini, Grok and DeepSeek models. Below: what Qwen3.8 Max is, what it wrote for our test brief, how it compares with the six other models we ran on the same prompt, a brief template that gets better output from it, and when another model is the better pick.
Try it: Open Marketing Agent, choose Qwen3.8 Max in the model picker, and paste the brief template from this guide. Open Marketing Agent →
What is Qwen3.8 Max?
Qwen3.8 Max is Alibaba's flagship large language model, announced on August 3, 2026 as the most capable model in the Qwen series so far. According to Alibaba's announcement and the Qwen team's launch post:
- It has 2.4 trillion parameters in a sparse mixture-of-experts design, with about 95 billion active for each request.
- It supports a context window of up to 1 million tokens. Alibaba Cloud's Model Studio page lists a maximum output of 131,072 tokens.
- Alibaba positions it mainly for coding and long-running agent work ("coding and cowork"), not specifically for marketing or copywriting.
- Developers can call it through the API on Alibaba Cloud Model Studio, where it accepts text, image and video input and returns text.
In BuzzVideo you don't need an Alibaba Cloud account or API key. The Marketing Agent model picker lists it as Qwen3.8 Max, described as "Top-tier quality at lower cost". It is the only Qwen model in the picker, and in our runs it showed no Thinking selector, unlike the Gemini and Grok models.
How did we test Qwen3.8 Max for ad copy?
On November 10, 2026, we sent one identical brief to seven Marketing Agent models in Auto mode, with Web Explore off and the default Thinking level where a selector was shown. The product is fictional:
“Text only, please don't generate any images or videos. I run ads for LUMEA, a fictional $38 vitamin C serum for US women aged 25-40, and our TikTok ads are fatiguing. 1) Give me 3 new hook angles, each with a first line under 10 words. 2) Pick the strongest one and write a 15-second UGC script as a table: time, shot, on-screen text, voiceover. 3) List 2 claims we must avoid for ad compliance, and why.”
- Test brief used for every model
We timed when the first text appeared and when the answer finished, and read the credit balance before and after each run. The balance came from a shared team workspace, so treat the credit figures as approximate.
What did Qwen3.8 Max write?
Qwen3.8 Max gave three hook angles, each with a named strategy, the insight behind it and a "4U" score (urgent, unique, ultra-specific, useful):
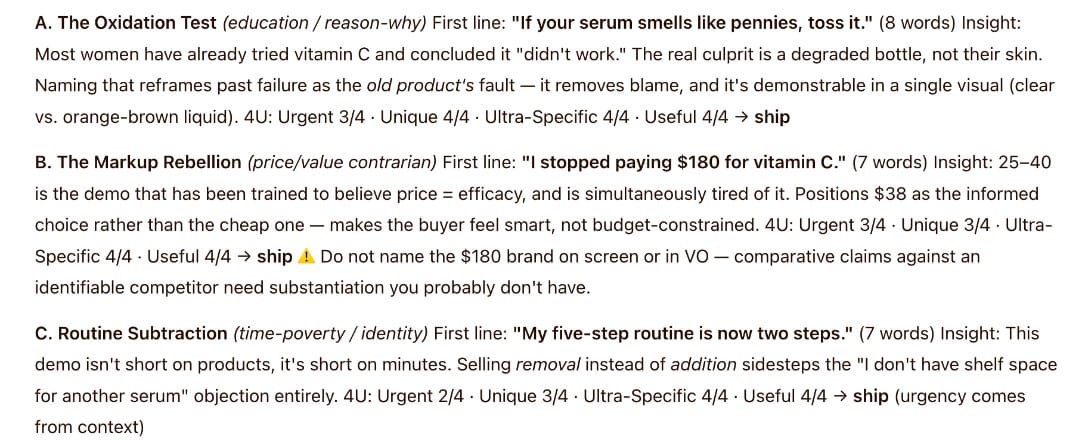
- The Oxidation Test: "If your serum smells like pennies, toss it." It reframes past failures as the old product's fault, not the viewer's skin.
- The Markup Rebellion: "I stopped paying $180 for vitamin C." It flagged its own risk: don't name the $180 brand, because comparative claims against an identifiable competitor need substantiation.
- Routine Subtraction: "My five-step routine is now two steps." It sells removing products rather than adding one.
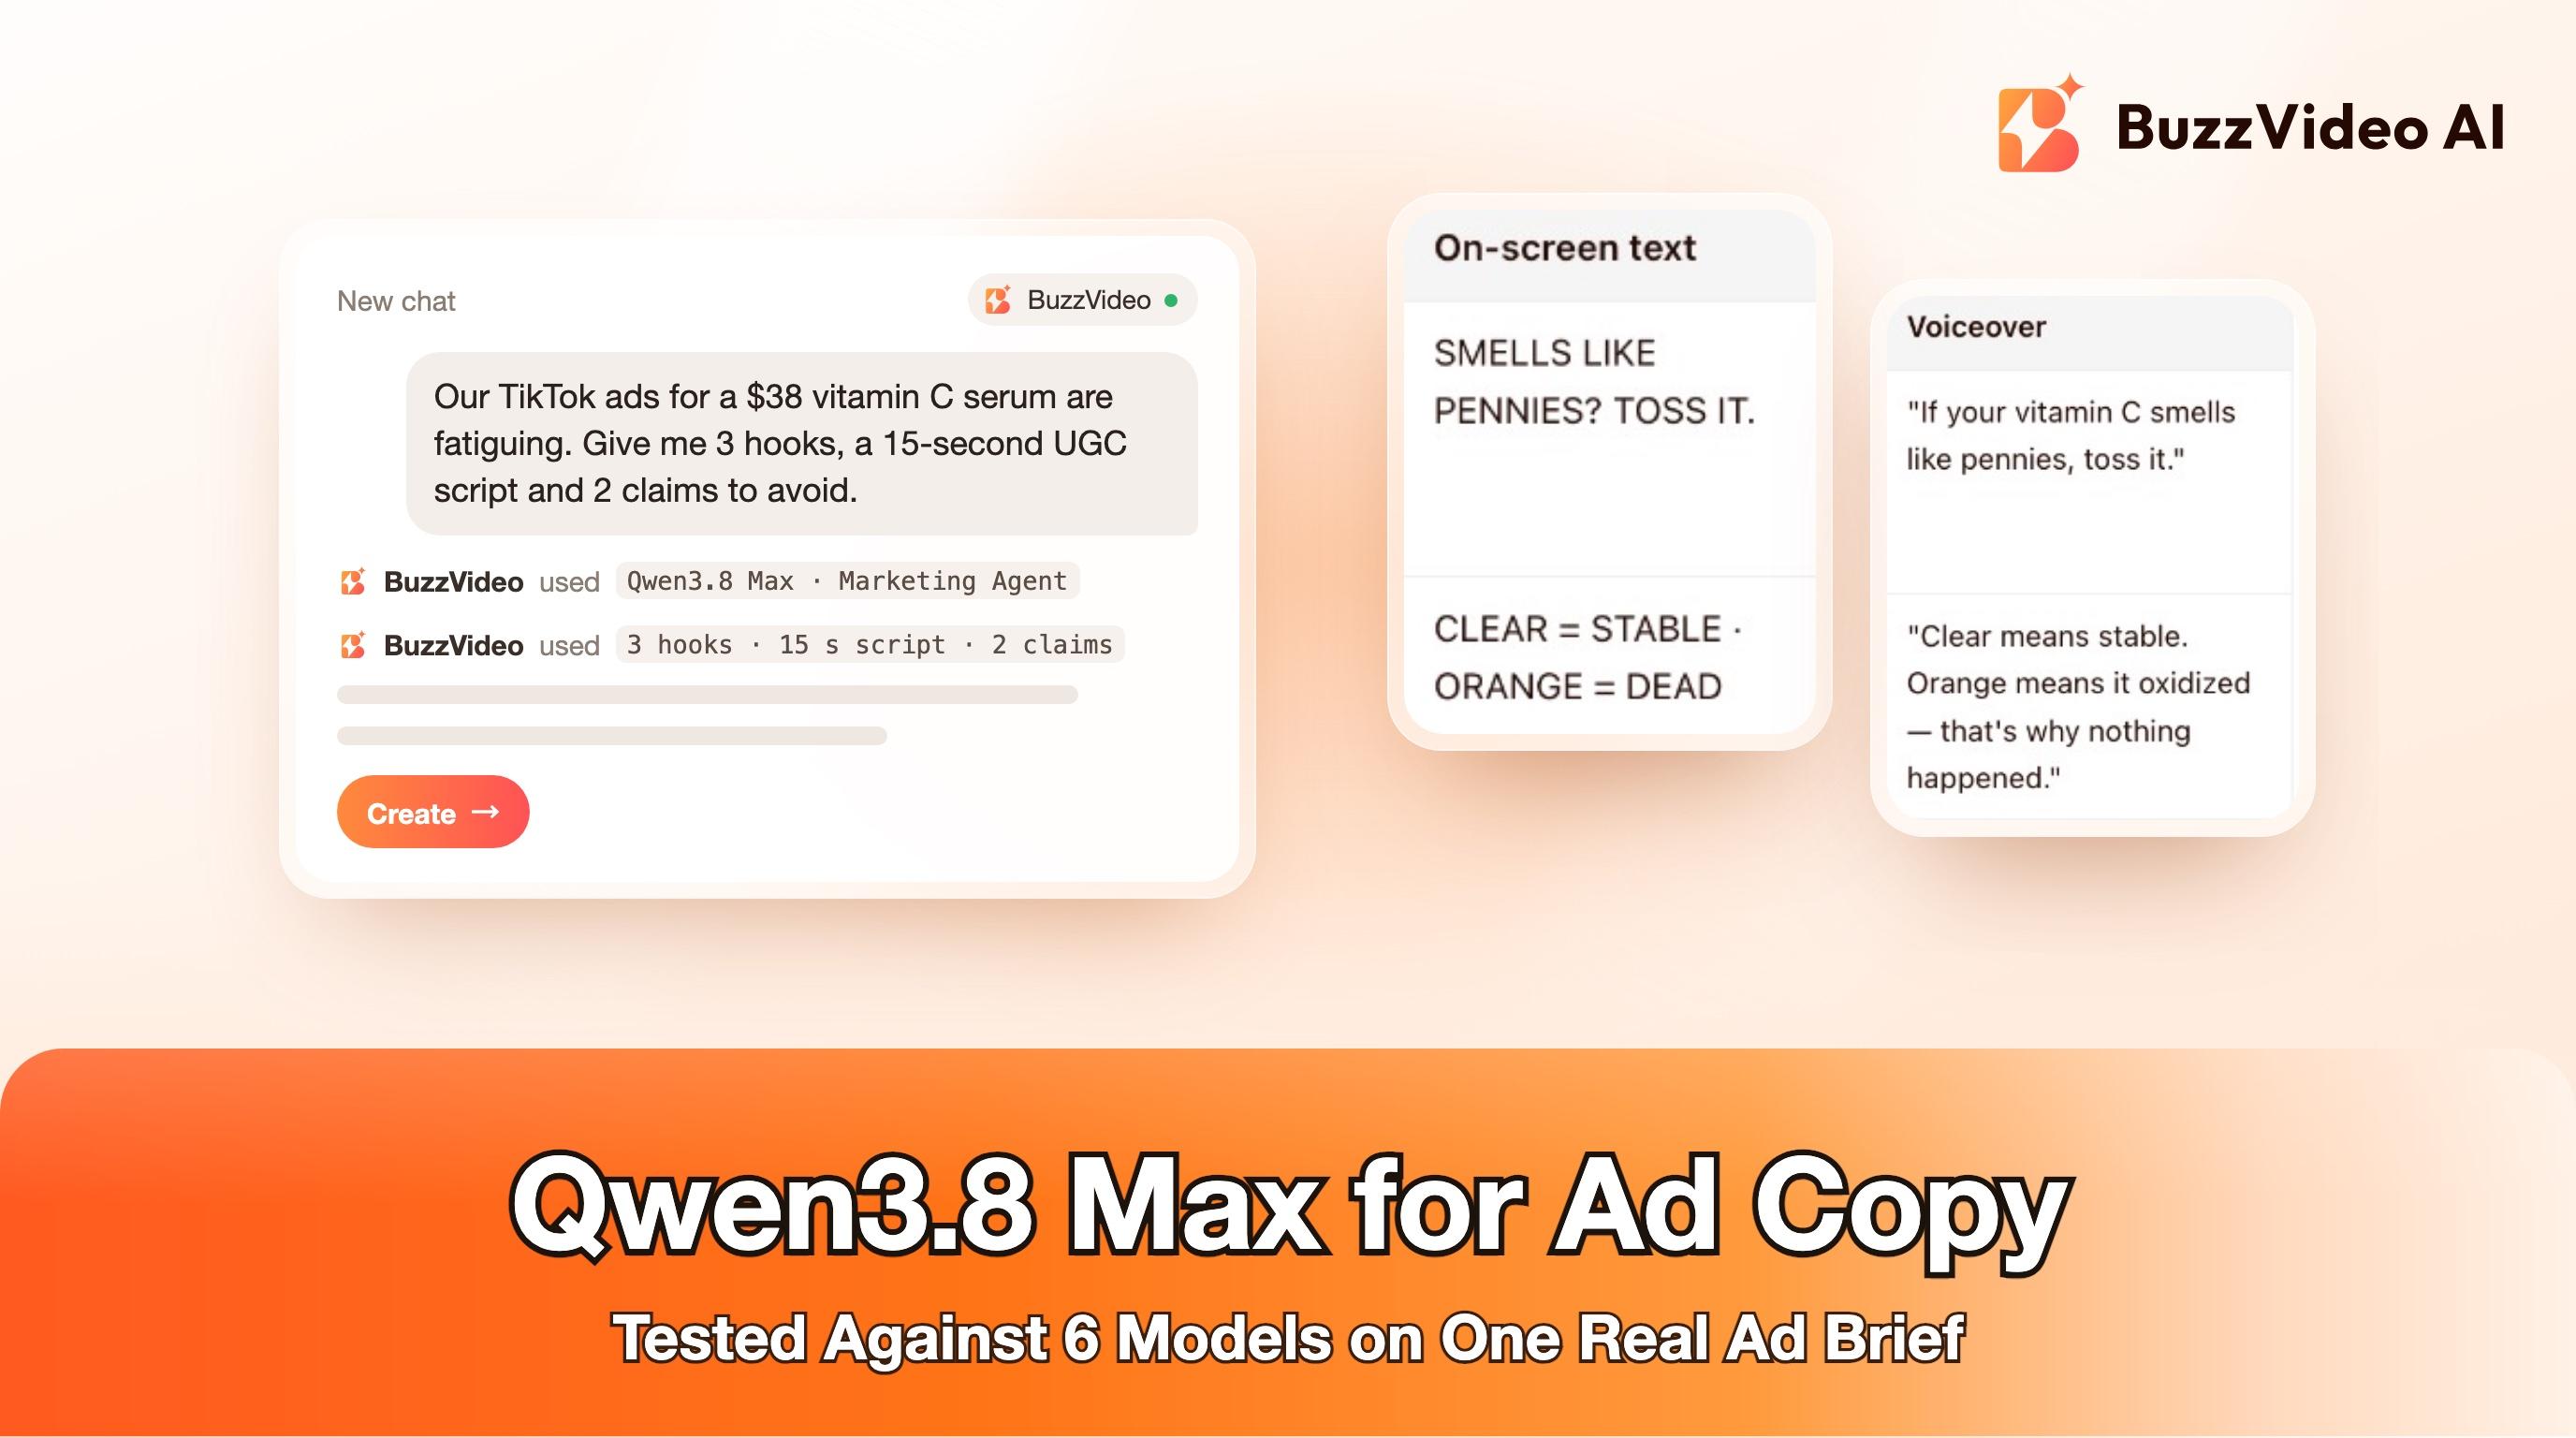
It picked the oxidation hook and wrote a five-beat script, labelling each beat by its job: pattern interrupt, mechanism, open loop, proof and a call to action ("Comment OXIDIZED"). It also set the register (raw UGC, handheld, bathroom-counter light, no logo in frame until 0:09).
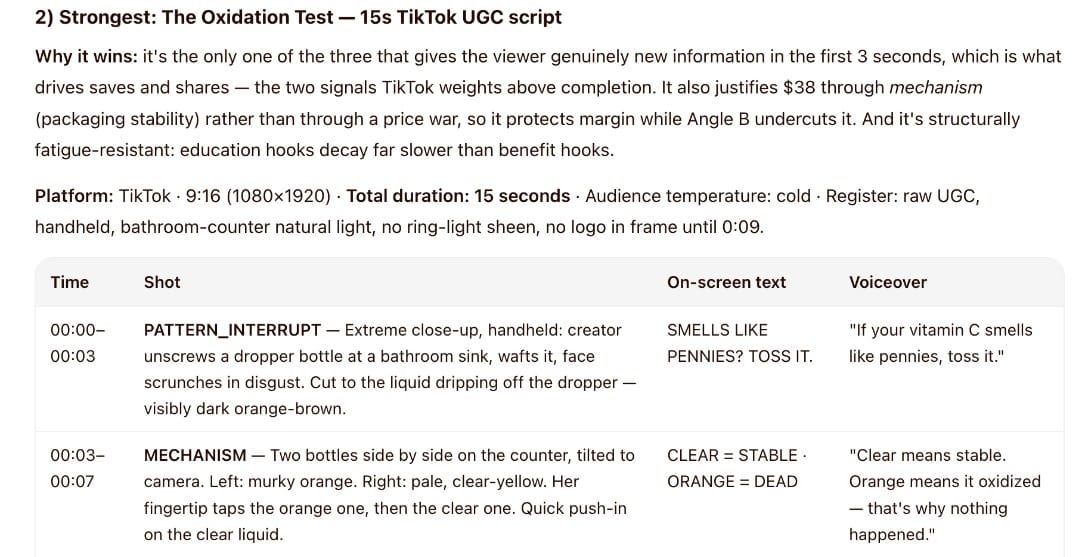
Then it went further than the brief asked. It added an 86-character caption, production notes (shoot three to five hook variants against one body, keep the audio bed about 15% under the voice-over), and a compliance section that covered disease and structure/function claims under the FD&C Act, guaranteed or time-bound results and before/after visuals under Section 5 of the FTC Act with a "results vary" disclosure, plus two bonus warnings: implied "clean" or "non-toxic" claims, and the #ad tag for paid creators.
Where Qwen3.8 Max went wrong
- It invented packaging. The script has the creator holding a "sealed amber pump", and the answer leans on an airless amber pump to justify the price. We never said what LUMEA comes in.
- The strongest line is also a claim. "Clear = stable · Orange = dead" implies LUMEA won't oxidize. That's only safe to run if you can show it.
- It's slow. About 90 seconds before the first word, and about 135 seconds in total.
The first problem wasn't unique to Qwen. Every model in our test made up at least one product fact, such as a pump, a percentage of vitamin C or a ferulic acid blend. The fix is in the brief, not the model choice: state the packaging, actives and claims you can prove.
Qwen3.8 Max vs DeepSeek, Gemini and Grok: which is best for ad copy?
| Model | First text | Total time | Credits (approx.) | Strength in our test | Watch-out |
|---|---|---|---|---|---|
| Qwen3.8 Max | ~90 s | ~135 s | ~29 | Most thorough: caption, variant plan, disclosure, #ad | Slow; invented an airless amber pump |
| Gemini 4 Argon | ~3.5 min | ~4 min | ~30 | Deepest reasoning, detailed FDA/FTC/TikTok notes | Slowest; invented packaging; stray line-break tags in the table |
| Gemini 3.8 Flash (default) | ~15 s | ~23 s | ~7 | Complete and fast | Invented 15% vitamin C + ferulic acid; added a scarcity line |
| Grok 4.7 | ~20 s | ~33 s | ~24 | Punchy six-word hooks, a "safe lane" rule | Implied stability claim |
| Grok 4.20 | ~15 s | ~21 s | ~6 | Cheapest Grok, fast | Generic hooks; script broke its own compliance rules |
| DeepSeek V4 Pro | ~13 s | ~29 s | ~12 | Structured; asks you to confirm before production | Hook claimed "I read 40 serum labels" |
| DeepSeek V4.1 Flash | ~27 s | ~34 s | ~2 | Best value, sharp compliance answer | Invented a sealed pump in dark glass |
Timings and credits from our runs in Marketing Agent on November 10, 2026, one run per model, same brief. Credits were read from a shared workspace balance, so they're approximate; chat is billed by usage, so your cost will vary with the length of the brief and answer.
Qwen3.8 Max vs DeepSeek V4 Pro. Both are the "deep" options from their vendors and neither showed a Thinking selector. DeepSeek V4 Pro finished in about 29 seconds for about 12 credits and stopped to ask for confirmation, which is handy when you want to steer. Qwen3.8 Max took over four times as long and cost more than twice as much, but handed back a fuller package: caption, variant plan and wider compliance notes. Pick DeepSeek V4 Pro for drafts, Qwen3.8 Max for the version you send to a creator.
Qwen3.8 Max vs Gemini 4 Argon. Similar credits, similar depth on compliance, but Qwen finished in a little over two minutes where Argon took about four. If you want a long, considered answer, Qwen was the faster of the two in our run.
Qwen3.8 Max vs the fast models. Gemini 3.8 Flash and DeepSeek V4.1 Flash answered in about half a minute for a fraction of the credits, and DeepSeek V4.1 Flash's compliance answer was as sharp as any. For rapid hook brainstorming, the fast models win. Despite its picker description, Qwen3.8 Max wasn't a low-cost option in our run.
How do you prompt Qwen3.8 Max for ad copy?
Qwen3.8 Max fills gaps with plausible detail, so the best way to use its thoroughness is to give it the facts up front and tell it what's off limits. This template adds what our test brief left out:
- Product facts. Price, size, packaging, key actives with percentages, and anything it must not describe differently.
- Provable claims. The claims you can substantiate, word for word. Ask it to use only these.
- Audience and platform. Who, where (US or UK), which placement and length.
- What's fatiguing. The angles you've already run, so it doesn't repeat them.
- Output format. Hooks with first lines, a script table, a caption, and compliance notes.
- Rules. No competitor names, no invented stats or testimonials, flag anything that reads as a claim.
Copy-paste brief template
“Text only. I run ads for [BRAND], a [PRICE] [PRODUCT] for [AUDIENCE] in [US / UK]. Product facts (use only these, don't add others): [PACKAGING], [SIZE], [KEY ACTIVES AND %], [TEXTURE / ROUTINE STEP]. Claims we can prove: [CLAIM 1], [CLAIM 2]. Our [TIKTOK / META] ads using [ANGLES ALREADY RUN] are fatiguing.
- Ad brief template for Qwen3.8 Max
1) Give me 3 new hook angles, each with a first line under 10 words.
2) Pick the strongest and write a [15]-second [9:16] UGC script as a table: time, shot, on-screen text, voiceover.
3) Write one caption under 100 characters.
4) List the claims in your script that need substantiation, and 2 claims we must avoid, and why.
Rules: don't name competitors, don't invent stats, studies, reviews or creator experiences, and mark any line that implies a result.”
Step 4 turns Qwen's compliance habit on its own script, which is where our test answer slipped. Treat what comes back as a checklist for your legal or brand review, not as legal advice.
When the script is ready, Marketing Agent can pass it to Generate Video in the same chat. For making the footage feel native, see how to make AI UGC ads that don't look fake.
When is Qwen3.8 Max not the right choice?
- You're brainstorming in quick rounds. A 90-second wait per reply adds up. Use Gemini 3.8 Flash or DeepSeek V4.1 Flash, then bring the winning angle to Qwen.
- You're producing variants at volume. At about 29 credits per brief in our run, DeepSeek V4.1 Flash (about 2) or Grok 4.20 (about 6) go much further. See how to ship 50 ad variants in a week.
- You need this week's trends. The Grok models are described in the picker as built for real-time trends and news.
- You want a short, punchy answer. Grok 4.7 gave the tightest copy; Qwen's answer is long and needs trimming before it goes to a creator.
If your ads use AI-generated people or footage, label them. Our guide to AI ad labels on Meta and TikTok covers what each platform asks for.
Want the most complete brief-to-script answer? Open Marketing Agent, pick Qwen3.8 Max, and start from the template above with your real product facts.
FAQs
Is Qwen3.8 Max good for marketing copy?
In our test it gave the most complete answer of seven models: three scored hooks, a five-beat script, a caption, production notes and compliance warnings. It was also slow and invented packaging details, so give it your real product facts.
How fast is Qwen3.8 Max in BuzzVideo?
In our run, the first text appeared after about 90 seconds and the answer finished after about 135 seconds. Gemini 3.8 Flash and DeepSeek V4.1 Flash finished the same brief in about 23 and 34 seconds.
How many credits does Qwen3.8 Max use?
Marketing Agent chat is billed by usage, so there is no fixed price per message. Our ad brief used about 29 credits, read from a shared workspace balance.
Qwen3.8 Max vs DeepSeek V4 Pro: which is better for ad copy?
DeepSeek V4 Pro was faster (about 29 seconds) and cheaper (about 12 credits) and asked for confirmation before production. Qwen3.8 Max was more thorough, adding a caption, a variant plan and broader compliance notes.
Does Qwen3.8 Max have a thinking mode in Marketing Agent?
Alibaba's API offers a thinking mode, but in our Marketing Agent runs Qwen3.8 Max showed no Thinking selector. The Gemini and Grok models do show one.
What is the context window of Qwen3.8 Max?
Up to 1 million tokens, according to Alibaba, with a maximum output of 131,072 tokens on Alibaba Cloud Model Studio.
Can I trust Qwen3.8 Max's compliance advice for US ads?
Use it as a starting checklist, not legal advice. It flagged FDA and FTC risks well, but its own script still contained an implied product claim.
Last verified: November 10, 2026, against our live pricing and product pages.
Next reads: Gemini 4 Argon vs 3.8 Flash · Grok for marketing · DeepSeek V4 Pro vs Flash · AI UGC ads that don't look fake · Ship 50 ad variants in a week · Label AI ads on Meta and TikTok · BuzzVideo pricing: cost per ad

About the author
Monica
Product Manager
As a Product Manager at BuzzVideo AI, I work with marketers and growth teams on AI ad workflows—from brief to shippable creatives. I write about practical product workflows, model choices, and how teams turn product pages into ads that feel native on Meta and TikTok.